Why CanyonOS

CanyonOS: One Platform for Scaling your Multi-Agent Apps

CanyonOS is an open-source platform that brings coherence and control to multi-agent workflows: design, deploy, scale, manage.

Agentic applications have matured rapidly and have crossed from demos into production. Most of that progress has been in the application layer, which is maturing fast: frameworks, model builders, prompts. Below it sits the infrastructure layer, already mature from the cloud era: Kubernetes, Docker, autoscalers, containers and queues. Mapping applications onto that infrastructure was always the job of DevOps teams, and it was a static exercise: decide the shape of the deployment once, then tune it. That is no longer feasible, because two underlying realities have changed. First, the applications are no longer deterministic. An agentic workflow decides at run-time which agents to call, how often, and what each call costs, so a static mapping is inefficient from the moment it is written. Second, the cost of that inefficiency is far higher than it used to be, because the compute these workflows run on is scarce and expensive.

CanyonOS automates the mapping. Its workflow intelligence layer sees every call made to an agent and uses that workflow-awareness to deploy, scale, trace and govern the workflow on the underlying infrastructure.

It does this through independent policy planes rather than through the code. Scaling, observability and governance each live in their own plane beside the workflow, so the workflow can evolve independently of its scaling, observability and governance policies, and each policy can change without touching the code.
The Problems We See in Agentic Development Today

Four problems, one per plane, and the same cause behind all of them.

Development plane

You should not need a new format for workflows. Python FTW.

A multi-agent workflow is usually a handful of agents and one loop. Today's frameworks make you express it through their own objects: nested wrappers, graphs and edges, crews and tasks, routing by string match. The result is hundreds of lines of orchestration before a single prompt or tool, and a different few hundred for every framework. The same workflow in plain Python is one file per agent and a short workflow file you can read top to bottom. Plain Python is neutral, importable into anything, understandable and timeless.

How CanyonOS answers it. The development plane stays yours. CanyonOS runs plain Python: agents are ordinary classes in ordinary files and the workflow is a program. There are no framework objects to learn and no code changes to make. One command, canyonos deploy, builds the images, launches the agents across machines and starts the dashboard; the only artefact added to your project is a small configuration folder, which is where the other planes live. Read more.

Scaling plane

Individual components of a workflow should scale to achieve the desired goals

Under load, queues build in front of the workflow and an autoscaler scales the whole workflow. This is often wasteful, since not all components of the workflow are under equal duress. The real bottleneck is usually downstream, in another agent or in a shared resource such as a test sandbox or a database, and the queue is only its symptom. Autoscalers see queues; they do not understand the relationship between them.

How CanyonOS answers it. The scaling plane. Because every call between agents passes through CanyonOS, it sees the dependency graph of the workflow: which component is waiting on which, and where the work is actually piling up. Scaling decisions are made from that graph rather than from a single queue, so capacity goes to the component or shared resource that is saturated, not to the one that happens to have a queue in front of it, and nothing in the code has to say so. Today CanyonOS ships per-agent autoscaling on queue length or throughput; the workflow-aware scheduler that scales from the dependency graph is the core of the Workflow Intelligence Layer and is in development. Read more.

Observability plane

Observability should be a by-product of inference

Tracing tools ask your code to carry them: imports, a provider and an exporter, a span around every call, attributes set by hand, trace context passed across every agent boundary, and a flush at the end. The workflow file can double in size, every agent file grows with it, and switching vendors means doing it all again with a different decorator.

How CanyonOS answers it. The observability plane. In CanyonOS the runtime is the tracer. Every agent-to-agent call is already a message through the runtime and every model call already passes through the gateway next to the agent, so traces, logs, tokens and cost are collected per query and per agent with no instrumentation in your code, and exported as OpenTelemetry to whatever dashboard you already use. Read more.

Governance plane

Governance should run concurrently with, and independently of, development

An agent that meets a bad input will reason about the failure and retry, and nothing in today's stack says stop. What frameworks offer are counters (iterations, rounds, steps), not policies: they count steps rather than dollars, they do not know which run they belong to, and they live in the code, so a new budget waits on a redeploy. Meanwhile the workflow changes every week. Governance has to be independent of development.

How CanyonOS answers it. The governance plane. CanyonOS puts policy in a file, not in code. A gateway beside every agent enforces which agents may call which model and the most one call may cost; a call that breaks policy is refused before it reaches the provider; the policy file is reloaded in seconds without a redeploy, so governance changes at its own pace, independent of development. Policy per workflow and per query, on the same plane, is next. Read more.

One Layer, Independent Planes

The four problems share one cause: nothing in today's stack sees the workflow, so the mapping onto infrastructure stays static and every concern ends up inside the code. CanyonOS's workflow intelligence layer does see the workflow, which is what lets it automate the mapping and move each concern into its own policy plane: scaling, observability and governance beside the workflow, not inside it. The workflow evolves at its own pace, and each policy at its own. CanyonOS is open source (AGPL-3.0) at github.com/CanyonCodeCoreAI/canyonos.

The Foundations

CanyonCode is built by people who have spent their careers on the two things this problem needs: distributed systems that run under real load, and AI products that reached production.

Founders

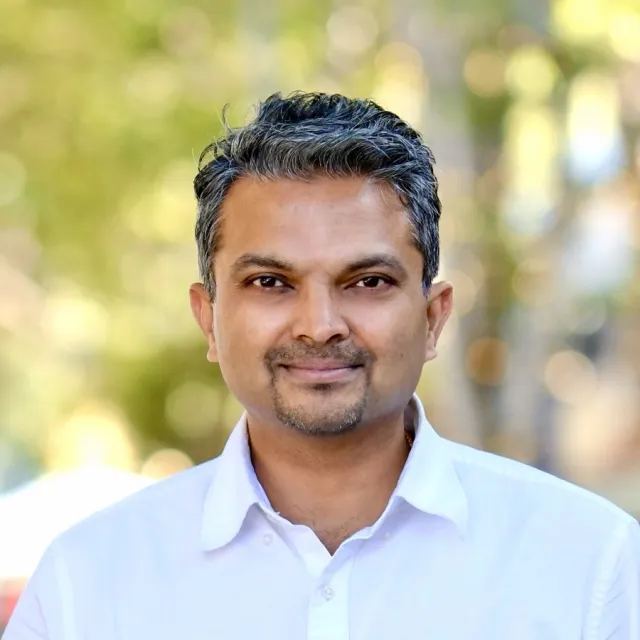
Ravikiran Gopalan

Ravikiran Gopalan

Co-founder and CEO

Dr. Ravikiran Gopalan is an entrepreneur with a background in AI and deep-tech innovation. Most recently he was co-founder and CTO of Aira Technologies (Series B), which pioneered GenAI-powered automation for network operations. He also co-founded Acuity.AI, an AI-powered video processing company acquired by Aira, while at Stanford Graduate School of Business. Before entrepreneurship Ravi spent multiple decades at Bell Labs and Qualcomm. He holds a master's in business from Stanford GSB and a PhD from the University of Notre Dame, and has been granted more than 50 patents.

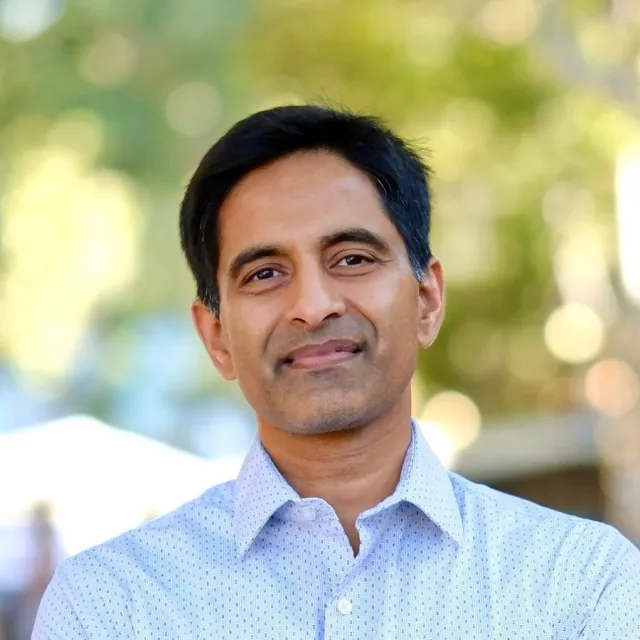
Aditya Akella

Aditya Akella

Co-founder

Aditya Akella is a Regents Chair in Computer Science and Professor at UT Austin and a researcher at Meta. His research spans computer systems and networking, with a current focus on systems and machine learning, programmable networks and formal methods in systems. He is known for his contributions to network support for AI, software-defined networking, systems for big data and AI, and programmable NICs; his work has influenced the infrastructure of some of the world's largest online and AI service providers. He is an ACM Fellow and has received the ACM SIGCOMM Test of Time Award, the SIGCOMM Rising Star award, the NSF CAREER award, the IRTF Applied Networking Research Prize, two UW-Madison Professor of the Year awards, two Blavatnik National Award finalist selections and several best paper awards.